

LLMs are here to stay, rule.
All your favorite companies are trying to put together some GenAI features in their products; some are successful, but most are struggling.
I am creating this guide for people who want to understand the process, nuances, and challenges of building AI products that really work.
This is created after dissecting a range of AI products, talking to real product managers and engineers at companies like Google, Meta, Glean, Microsoft, PayTM, building AI products myself, and teaching over 2500 folks about AI Product Management.
You can also consume the lessons from this guide as videos from our free AI PM program.
It’s a long guide. Feel free to read it at once or in chunks.
Here’s how I’ve organized it:
Part 1: Before you build anything
What kind of AI products are we talking about?
AI Product Sense. Is it real?
Part 2: The Core Tech (I’ve tried to make it approachable)
LLMs. What you actually need to know.
The nature of LLM-based products.
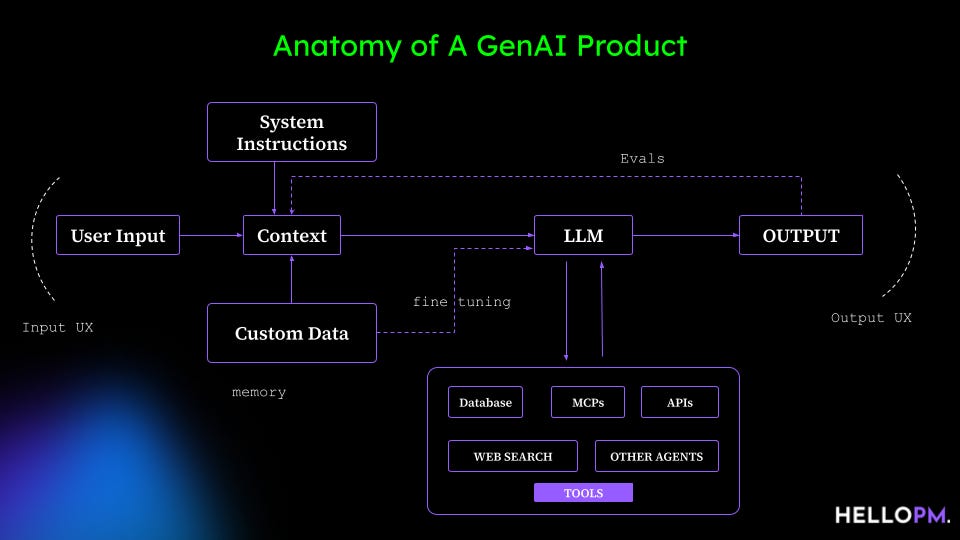
Anatomy of a GenAI product. How your meeting assistant actually works.
Part 3: The Builder’s Toolkit
Prompt engineering and in-context learning.
The rules of RAG.
How Notion AI and Cursor actually work.
Fine-tuning and when it actually makes sense.
Part 4: Agents and The Next Wave
Introducing Agentic AI.
Building AI Agents. How Deep Research works.
Why agents break (and how to fix them).
Part 5: The unglamorous reality
Cost, latency, and the tradeoffs nobody talks about.
Evaluations. The skill that separates serious builders from everyone else.
Part 6: Putting it All Together
The full picture. From idea to production.
Next steps for you.
Let’s get into it.
Part 1: Before You Build Anything
1. What kind of AI products are we talking about?
First things first. When I say “AI products,” I’m not talking about recommendation engines at Netflix or fraud detection at your bank. Those are ML products. They’ve existed for years. They’re important, but they’re not what this guide is about.
This guide is about LLM-powered products. Products that use large language models as their core intelligence layer. Think ChatGPT, Cursor, Harvey, Granola, NotebookLM, Notion AI.
And within LLM products, there’s an important distinction most people miss.
AI-native products are built from the ground up around an LLM. The product doesn’t make sense without the AI. ChatGPT is the obvious example. Cursor is another one. Harvey, the legal AI company now valued at $8 billion with 700+ clients across 63 countries, is another. Remove the LLM and the product ceases to exist.
AI-augmented products bolt AI features onto an existing product. Notion AI is a good example. Notion existed and thrived long before they added AI writing assistance. The AI is a powerful addition, but the product’s core value isn’t dependent on it.
Why does this matter? Because the approach to building each is fundamentally different.
With AI-native products, you’re designing the entire user experience around the LLM’s capabilities and limitations. Your UX, your pricing, your error handling, your evaluation metrics, everything starts with the model.
With AI-augmented products, you’re fitting AI into an existing user workflow. The challenge here is integration. How do you add AI in a way that feels natural and actually useful, not just a checkbox feature so your CEO can say “we have AI now”?
Both are valid. Both are interesting. But know which one you’re building before you write a single prompt.
The GenAI Value Stack:
There’s also a value stack worth understanding.
Infrastructure (GPUs, TPUs). Nvidia is making billions here.
Models (LLMs, SLMs). OpenAI, Anthropic, Google, Meta building the actual models.
Applications (tools built on models). Products like Cursor, Granola, Harvey.
Agency (autonomous agent layer). The emerging frontier.
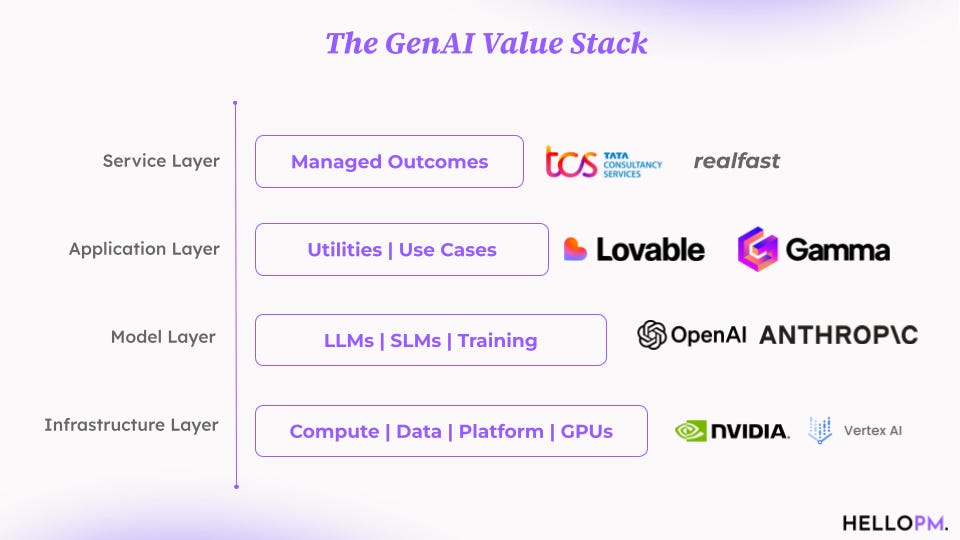
Most of you reading this will be building at the application or agency layer. That’s where the biggest opportunity is right now, and that’s where this guide focuses.
A quick practical test before you start building: Ask yourself these three questions about the AI feature you’re planning:
Can a human do this task in under 30 seconds? If yes, you probably don’t need AI. You need better UX.
Is the cost of being wrong low? If the AI gets it wrong, does the user lose 5 seconds (they can retry) or $5,000 (they made a bad decision)? This determines how much guardrails you need.
Does the user have enough context to judge the AI’s output? A developer can tell if the generated code is good. A patient can’t tell if a medical diagnosis is correct. This determines your human-in-the-loop strategy.
If you can’t answer these questions, you haven’t done enough discovery. Go back and talk to users.
2. AI Product Sense. Is it real?
Every product manager talks about “product sense.” It’s that ability to accurately predict what your users and the market will value. You develop it through experience, research, and pattern recognition.
But here’s the question nobody’s asking clearly enough: does product sense work differently when the product is non-deterministic?
The answer is yes. And understanding why changes how you build.
Traditional products are deterministic. You click a button, the same thing happens every time. You can QA every edge case. You can guarantee behavior. If something breaks, you can reproduce the bug.
LLM products are non-deterministic. The same input can produce different outputs. You can’t guarantee behavior. You can’t QA in the traditional sense. And reproducing bugs? Good luck. The model might not give you the same wrong answer twice.
I use this analogy a lot: think about chai. If you make chai at home with the same ingredients, same method, same stove, you’ll get roughly the same cup every time. Now make chai at a roadside stall on the highway. Then at a hill station. Then on Indian Railways. Same ingredients, wildly different results every time. That’s what building with LLMs feels like.
So AI product sense is real, but it requires a few additional muscles that traditional PMs don’t typically develop:
1. Tolerance for ambiguity in output quality. Your product will sometimes give brilliant answers and sometimes hallucinate garbage. You need the instinct to know what “good enough” looks like for your specific use case. A creative writing tool can tolerate 80% quality. A medical summary needs 99%+. Know your number.
2. Evaluation thinking. Traditional PMs think in terms of pass/fail. AI PMs think in terms of distributions. “This prompt gives accurate answers 87% of the time” is a statement you need to be comfortable making decisions with. If that sentence makes you uncomfortable, this guide will fix that.
3. Knowing where to put the human in the loop. The best AI products aren’t fully autonomous. They’re designed with specific points where human judgment takes over. Here’s the practical framework:
High stakes + Low confidence = Human decides, AI suggests. (Harvey showing flagged clauses to lawyers)
Low stakes + High confidence = AI decides, human can override. (Gmail’s Smart Reply)
High stakes + High confidence = AI drafts, human approves. (Cursor generating code that the developer reviews)
Low stakes + Low confidence = Don’t use AI. Seriously. If the AI can’t be confident and the task doesn’t matter enough to justify AI costs, just build a regular feature.
4. Understanding model limitations as design constraints. A good architect works with the properties of their materials, not against them. Here’s what LLMs are actually good and bad at:
Good At Bad At Summarization Precise math Translation Real-time data Text generation Consistent formatting Classification Counting (words, characters) Pattern matching Maintaining state across turns Code generation Citing sources accurately Sentiment analysis Saying “I don’t know”
Build your product around the left column. Engineer around the right column. Don’t fight the technology.
Always remember: 80% of being a good AI PM is still being a good PM.
Discovery, user research, prioritization, stakeholder management. The AI-specific knowledge is the remaining 20%. But that 20% is where most people get stuck. And that’s what the rest of this guide is about.
Part 2: The Core Tech (Without the PhD)
1. LLMs. What you actually need to know.
You don’t need to understand transformer architectures or attention mechanisms to build great AI products. What you need to understand is the practical reality of how these models work so you can make better product decisions.
Here’s the one thing you need to know: LLMs are next-token predictors. That’s it. They take a sequence of text, and they predict the most likely next word (technically, next “token”). They do this one token at a time, over and over, until they’ve generated a complete response.
This single fact explains almost everything about LLM behavior. Let me show you.
Why do they hallucinate? Because they’re predicting the most probable next token, not the most accurate one. If the model has seen enough text where a false claim appeared plausible in context, it’ll predict that false claim. It’s not lying. It’s pattern-matching. The model would rather generate a plausible-sounding falsehood than stop and say “I don’t know,” because in all the training data it saw, humans rarely did that.
Why do they sometimes give different answers to the same question? Because there’s a randomness parameter called temperature that controls how strictly the model follows its probability distribution. At temperature 0, the model always picks the highest-probability token. Deterministic, but often boring and repetitive. At temperature 0.7-1.0, it samples from the probability distribution, introducing variety. For a product builder, this means:
Customer support bot? Temperature 0.1-0.3. You want consistency.
Creative writing tool? Temperature 0.7-0.9. You want variety.
Code generation? Temperature 0.0-0.2. You want correctness.
Brainstorming helper? Temperature 0.8-1.0. You want surprise.
Getting this wrong is one of the most common mistakes I see. Teams ship creative features with temperature 0 (outputs are stale and robotic) or factual features with temperature 1.0 (outputs are creative but wrong).
Why do they get worse with really long prompts? Because of something called “attention.” When the model processes tokens, it checks each token against every other token to understand context. More tokens means more attention checks, which means the model’s focus gets diluted. Think of it like asking someone to keep track of 10 things vs. 10,000 things. Quality drops. Specifically, research shows models struggle with information in the “middle” of long contexts. The first and last parts of a prompt get the most attention. If you’re stuffing 5,000 tokens of context into a prompt, put the most important information at the beginning and the end.
Tokens: the currency of LLMs.
Every interaction is measured in tokens. Input tokens (what you send to the model) and output tokens (what the model generates back). Pricing, latency, memory, everything is counted in tokens.
Practical rules of thumb:
1 token is roughly 3/4 of a word in English
A typical paragraph is ~100 tokens
A full page of text is ~500 tokens
The average ChatGPT query is 500-5,000 input tokens
The average response is 100-1,000 output tokens
Output tokens are typically 3-5x more expensive than input tokens
This matters because every token you add to a prompt needs to justify its ROI. I’ve seen teams stuff 5,000 tokens of instructions into their system prompt and then wonder why their product is slow and expensive. That 5,000-token system prompt gets sent and billed on EVERY SINGLE user query. At GPT-4o rates (~$2.50/million input tokens), 5,000 tokens across 100,000 daily queries costs ~$1,250/day just for the system prompt alone. Before the user has even typed a word.
Embeddings: how LLMs understand meaning.
When text goes into an LLM, it’s converted into embeddings, numerical vectors that represent semantic meaning. Similar concepts end up close together in this vector space. “Dog” and “cat” are close together (both domesticated animals). “Dog” and “quantum physics” are far apart.
Why should you care? Because embeddings are the foundation of search and retrieval in AI products. When you hear people talk about “vector databases” and “semantic search,” they’re talking about storing and searching these embeddings. A user types “how do I cancel my subscription” and the system finds chunks about “cancellation policy” and “ending your membership” even though none of those words match exactly. That’s embeddings at work.
The three phases of building an LLM:
Pre-training: Feed massive amounts of internet text. Model learns language patterns. (Costs: $10M-$100M+. You’re not doing this.)
Training/Supervised Fine-tuning: Input-output pairs teach the model to follow instructions. (Costs: $100K-$1M. You’re probably not doing this either.)
Post-training/RLHF: Safety alignment, instruction tuning. Raw text predictor becomes a helpful assistant. (This is where the model’s “personality” gets shaped.)
You don’t need to do any of these phases yourself. OpenAI, Anthropic, Google, Meta have done it for you. Your job is to use these models effectively. But understanding that these phases exist helps you understand why different models behave differently. Claude tends to be more cautious and follow instructions precisely. GPT tends to be more creative and conversational. Gemini tends to handle multimodal inputs (images, video) better. These are post-training personality differences.
One final point. Models are getting commoditized. After DeepSeek showed that you could build competitive models at a fraction of the cost, the moat is no longer “who has the best model.” The moat is product experience, proprietary data, and distribution. Harvey’s moat isn’t GPT. It’s their understanding of legal workflows and their relationships with 700+ law firms. Cursor’s moat isn’t Claude. It’s their codebase indexing system and developer UX. Remember this when someone tells you to “just build on GPT.” The model is the least defensible part of your stack.
2. The nature of LLM-based products.
Building with LLMs is fundamentally different from building traditional software. If you come from a traditional product background, here are the specific things you need to rewire.
Non-determinism is the core challenge. When you call an API endpoint in traditional software, you know exactly what response you’ll get. When you call an LLM, you know roughly what kind of response you’ll get, but the exact output is unpredictable. This single difference changes everything about how you design, test, ship, and iterate.
Here’s what this means in practice. I ran the same prompt through GPT-4o five times:
Prompt: “Summarize the key features of Notion AI in 3 bullet points.”
I got five different summaries. All correct. All different structure, different emphasis, different word choices. Three mentioned pricing. Two didn’t. One was 45 words. Another was 120 words.
Now imagine you’re building a product that generates meeting summaries for 100,000 users daily. Each summary is different. You can’t manually review them. You can’t guarantee quality. You need a system to manage this. That system is evaluations, and we’ll go deep on it in Part 5.
Hallucinations are a feature, not a bug. I’m serious. The same mechanism that lets LLMs generate creative, coherent, surprisingly insightful responses is the same mechanism that causes hallucinations. They’re both products of probabilistic text generation. You can reduce hallucinations, but you can’t eliminate them without eliminating the model’s generative capability.
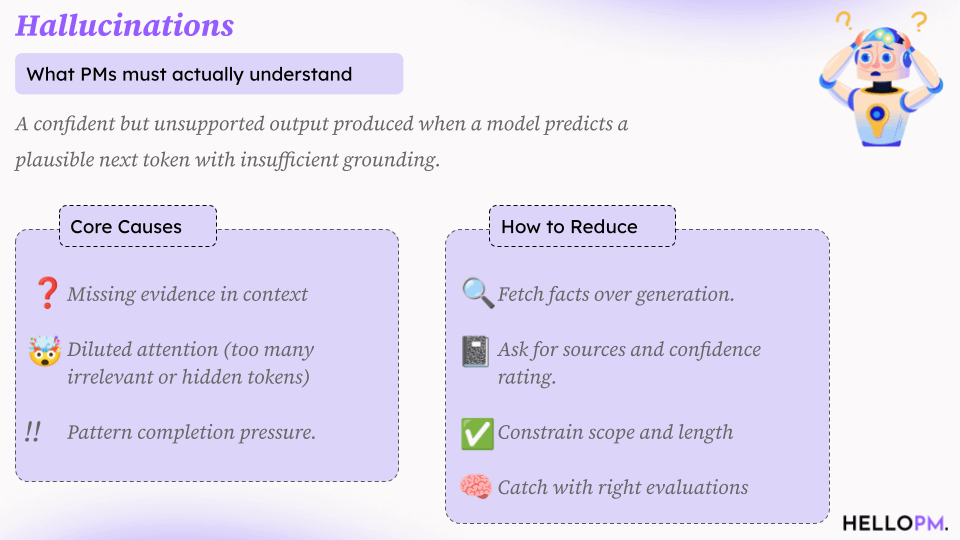
Seven practical techniques to reduce hallucinations:
Add “I don’t know” as an explicit option. In your system prompt: “If you do not have sufficient information to answer accurately, respond with ‘I don’t have enough information to answer this reliably’ and explain what additional context would help.” Most models will never say this unprompted. You have to give them permission.
Supply grounding context. This is what RAG does (covered in detail in Section 7). Give the model the specific documents, data, or context it should base its answer on, and tell it to only use that context.
Use Chain-of-Thought. Ask the model to explain its reasoning before giving a final answer: “Think through this step-by-step, then provide your answer.” This forces the model to show its work, and you can often spot where the reasoning goes wrong before the final answer does.
Keep prompts focused. Don’t ask the model to do 10 things at once. Break complex tasks into smaller, sequential steps. Each step has fewer tokens, clearer instructions, and less room for the model to drift.
Request citations. “Cite the specific paragraph from the provided context that supports your answer.” When the model has to point to where it got the information, it’s much harder for it to hallucinate. And if it can’t cite a source, that’s your signal that it’s making something up.
Implement output validation. After the model generates a response, run automated checks. Does the URL actually exist? Does the mentioned product feature actually exist in your docs? Is the number within a plausible range? These code-based checks catch a surprising number of hallucinations.
Use a second model as a fact-checker. This is the “LLM-as-judge” pattern. Have one model generate, and a second model evaluate the output for accuracy against the provided context. Yes, this doubles your API costs. For high-stakes use cases, it’s worth it.
Latency is a UX problem, not just an engineering problem. LLMs are slow compared to traditional APIs. A database query returns in milliseconds. An LLM response can take 2-15 seconds depending on the model and output length. Two metrics matter:
Time to First Token (TTFT): How quickly the user sees the first word appear. This is the metric users feel most. If nothing happens for 5 seconds, they think the product is broken. Target: under 1-2 seconds for chat-style products.
Tokens per second: How fast the rest of the response streams in. Target: 30-80 tokens/second for a good reading experience.
Practical latency tricks:
Stream responses. Don’t wait for the complete response before showing anything. Show tokens as they generate. Every major AI product does this.
Show progress indicators. “Searching your documents...” “Analyzing the contract...” “Generating your summary...” Tell users what’s happening.
Prefetch when possible. If you can predict what the user will ask next, start generating before they ask. Cursor does this with code completions.
Use smaller models for fast tasks. Route simple classification or extraction tasks to GPT-4o-mini (TTFT ~200ms) instead of GPT-4o (TTFT ~800ms). Users won’t notice the quality difference for simple tasks, but they’ll notice the speed difference.
Every query costs money. In traditional SaaS, adding one more user costs almost nothing. In LLM products, every query consumes tokens, and tokens cost real money. This changes everything:
Your pricing strategy (can’t offer unlimited queries at a flat rate unless you’re burning VC money)
Your usage limits (free tiers need query caps)
Your feature design (do you generate a full report or a summary? The report costs 10x more)
Your model selection (do all queries need GPT-4, or can 80% be handled by GPT-4o-mini at 1/15th the cost?)
We’ll go deep on cost optimization in Part 5.
3. Anatomy of a GenAI product. How your meeting assistant actually works.
Let’s break down a real product. I’m going to use Granola, the AI meeting assistant, because it’s a beautifully designed product that illustrates every concept we’ve talked about, and because the architectural decisions they made reveal how good product thinking applies to AI.
Granola raised $67 million at a $250 million valuation. It’s become a favorite among tech leaders, VCs, and senior executives. Here’s what’s actually happening under the hood.
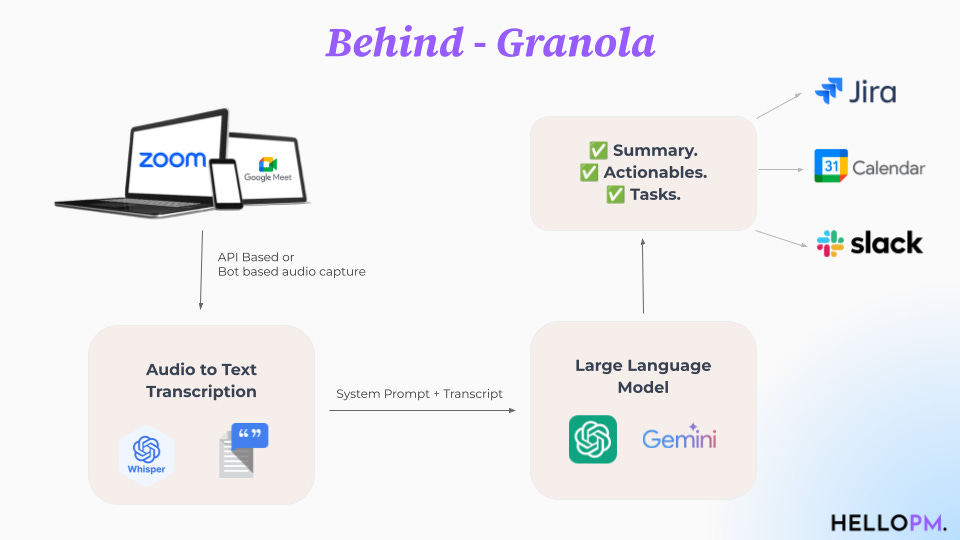
Step 1: Audio Capture (The Input Layer)
When you join a video call on Google Meet, Zoom, or Teams, Granola runs quietly in the background on your device. No bot joins your call.
This is a huge product decision. Most competing tools (Otter, Fireflies, tl;dv) add a visible recording bot to your meeting. That bot makes participants uncomfortable, often gets rejected by meeting hosts, and costs money to run (it’s essentially a remote participant consuming compute on the video platform).
Granola captures audio directly from your device’s microphone output. The audio is transcribed locally and then deleted. They never store recordings. This architectural choice gives them three advantages:
Trust: No creepy bot. No stored recordings. Users feel safer.
Cost: No cloud audio storage, no video processing pipeline. They cut three major cost drivers.
Compliance: They achieved SOC 2 certification in three months instead of the typical 12-18 months because their architecture simply doesn’t retain audio.
Step 2: Transcription (Processing Layer 1)
Audio is converted to text in real-time using speech-to-text models (not an LLM, a specialized transcription model). This is an important detail. You don’t use an LLM for everything. Speech-to-text is a solved problem with dedicated models that are faster and cheaper than general-purpose LLMs.
Step 3: The Hybrid Notepad (UX Innovation)
While the meeting runs, you jot rough notes in Granola’s notepad. This is the core UX insight that makes Granola different from every other meeting tool. You’re not a passive consumer of AI-generated notes. You’re an active participant, writing your own notes, which the AI then enhances.
After the meeting, Granola’s LLM takes your rough notes AND the full transcript. Your original notes appear in black text. The AI-added context appears in gray. You see exactly what you wrote and what the AI added. If the AI hallucinated something, you’d notice because it’s visually separated from your own words.
This is human-in-the-loop design at its best. The user maintains agency. The AI assists, it doesn’t replace.
Step 4: Post-Meeting Intelligence (RAG in Action)
When you ask Granola a question after the meeting (”What did Sarah say about the budget?”), it doesn’t send the entire 60-minute transcript to the LLM. That would be ~15,000 tokens per query, expensive and slow.
Instead: the transcript is chunked, vectorized, and stored. Your question gets converted to a vector, matched against the transcript chunks, and only the relevant 500-1,000 tokens get sent to the LLM alongside your question. This is RAG, and it’s how every “chat with your data” feature works.
Step 5: Memory Across Meetings (The Compound Effect)
Granola now surfaces context from previous meetings when you meet with the same person again. This is where the product goes from useful to indispensable. Before your 1:1 with a direct report, Granola shows what you discussed last time, what action items were assigned, and what’s still open. This is a vector database + metadata search across all your meetings, filtered by participant.
The formula at work:
Input → [Speech-to-Text + LLM + RAG + System Prompt + UX] → Output
This formula applies to almost every GenAI product. The specific components change, but the structure is the same. When you’re building your own product, think of these as “knobs” you can turn. Change the model, change the prompt, change the retrieval strategy, change the UX, and you get a different product even with the same underlying architecture.
The building blocks applied to other products:
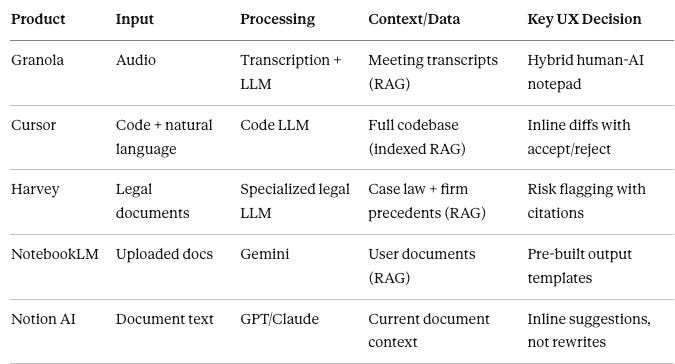
Study this table. Every product is the same formula with different knob settings.
Part 3: The Builder’s Toolkit
1. Prompt engineering and in-context learning.
This is where most teams start building. And honestly, this is where most teams can get 80% of the way to a good product. Before you think about RAG, fine-tuning, or agents, master this.
Every GenAI product you use is, at its core, built on prompts. ChatGPT has a system prompt. Cursor has a system prompt. Harvey has a system prompt. Notion AI has a system prompt. The system prompt is arguably the most important piece of code in your entire product.
The two-part prompt structure:
System Prompt: Hidden instructions from the product. Defines behavior, constraints, output format. The user never sees this.
User Prompt: What the user types. The query, request, or task.
Most developers understand this. But most developers also write terrible system prompts. Here’s how to write good ones.
The 7 components of a production system prompt:
1. Role/Persona. Who is the AI in this product?
Bad: "You are a helpful assistant."
Good: "You are a senior contract attorney with 15 years of experience
reviewing commercial agreements. You specialize in identifying
liability clauses, indemnification gaps, and non-standard terms."
The more specific the persona, the better the outputs. “Helpful assistant” is what you get with zero effort. A specific role grounds the model’s behavior in a domain.
2. Task definition. What exactly should the AI do?
Bad: "Help the user with their questions."
Good: "Review the provided contract and produce:
1. A list of all clauses that deviate from our standard template
2. A risk rating (Low/Medium/High) for each deviation
3. Suggested alternative language for High-risk deviations
4. A 3-sentence executive summary"
Be specific about the output structure. If you want 3 bullet points, say so. If you want JSON, specify the schema. Don’t leave formatting to chance.
3. Rules and constraints. What should the AI NOT do?
- Never provide specific legal advice. Always recommend consulting
  with a qualified attorney for legal decisions.
- Never disclose information about other users or their documents.
- If a clause is ambiguous, flag it as "Requires Human Review"
  rather than guessing at the interpretation.
- Never hallucinate contract terms. Only reference clauses that
  actually appear in the provided document.
- Keep responses under 500 words unless the user specifically
  asks for more detail.
Explicit negatives are just as important as positives. If you don’t tell the model what NOT to do, it will eventually do it.
4. Few-shot examples. Show, don’t just tell.
This is one of the most powerful and underused techniques. Instead of describing what you want in abstract instructions, show the model 2-3 examples of ideal input-output pairs.
Example 1:
Clause: "Vendor shall indemnify Client against all third-party claims."
Analysis: Risk: Medium. This clause provides broad indemnification but
lacks carve-outs for Client's own negligence.
Suggestion: Add "except to the extent arising from Client's gross
negligence or willful misconduct."

Example 2:
Clause: "This agreement auto-renews for successive 1-year terms."
Analysis: Risk: Low. Standard auto-renewal language. Ensure 30-day
notice period for non-renewal is specified elsewhere in the agreement.
Suggestion: No changes needed.
Two to three examples is usually sufficient. More than five and you’re wasting tokens. The examples should cover the range of expected outputs: a positive case, a negative case, and an edge case.
5. Output format specification.
Respond in the following JSON format:
{
  "clauses": [
    {
      "clause_text": "exact text from the contract",
      "risk_level": "Low | Medium | High",
      "analysis": "1-2 sentence explanation",
      "suggestion": "alternative language or 'No changes needed'"
    }
  ],
  "executive_summary": "3 sentences max"
}
Structured output is critical when your AI’s response feeds into downstream systems (a UI, a database, another API call). Without explicit format instructions, models default to conversational prose that’s hard to parse programmatically.
6. Context handling instructions. Tell the model how to use the context you provide.
You will be given a contract document between <contract> tags.
Base ALL of your analysis exclusively on this document.
Do NOT reference external legal standards or precedents unless
they are explicitly mentioned in the document.
If the document does not contain sufficient information to
assess a particular risk, respond with "Insufficient information
in the provided document."
This is where XML/HTML tags as delimiters become important. Tags like <contract>, <context>, <instructions> help the model distinguish between different parts of the prompt. It’s like adding section headers to a document. The model parses structured input much more reliably.
7. Fallback behavior. What should happen when things go wrong?
If you encounter any of the following, respond accordingly:
- Document is not a contract: "This doesn't appear to be a contract.
  Please upload a legal agreement."
- Document is in a language other than English: "I currently only
  support English-language contracts."
- Document is too short to analyze (under 100 words): "This document
  appears incomplete. Please upload the full contract."
- User asks a question unrelated to contract review: "I'm specialized
  in contract review. For other questions, please contact support."
Most teams skip fallback behavior and then wonder why their chatbot tries to write poetry when a user sends a random query.
Advanced prompting techniques that actually work in production:
Chain-of-Thought (CoT). Add “Think through this step-by-step before providing your final answer” to your system prompt. This forces the model to reason before concluding. In production, you might hide the reasoning from the user and only show the final answer, but the reasoning step measurably improves accuracy. One implementation I’ve seen: generate the CoT, validate it with a second prompt, then extract the final answer.
Prefilling. Some APIs (Claude, in particular) let you start the assistant’s response with specific text. If your system prompt says “respond in JSON,” but the model sometimes starts with “Sure! Here’s the JSON:”, you can prefill the response with { to force it to start with valid JSON immediately.
Negative examples. Show the model what bad output looks like and tell it to avoid that pattern:
DO NOT respond like this:
"I'd be happy to help! Here's a comprehensive analysis of your
contract. There are several important points to consider..."
(too verbose, filler language, no structure)

DO respond like this:
{"clauses": [{"clause_text": "Section 4.2...", "risk_level": "High"...}]}
(structured, concise, actionable)
One final prompting principle: shorter is not always better, but unnecessary tokens are always worse. Every token in your system prompt costs money on every query. A 2,000-token system prompt across 100,000 daily queries at GPT-4o rates costs ~$500/day. But cutting tokens at the cost of clarity is a false economy. A clear 2,000-token prompt that produces accurate results will save you more than a vague 500-token prompt that produces garbage requiring re-prompting and human review. Optimize for output quality first, then trim unnecessary tokens.
2. The rules of RAG.
RAG (Retrieval-Augmented Generation) is one of the most important concepts in this entire guide. If prompt engineering is how you tell the LLM what to do, RAG is how you give it the information it needs to do it well.
Here’s the core problem: LLMs are trained on historical data. They don’t know about your company’s internal documents, your product’s knowledge base, last week’s meeting notes, or this morning’s news. Their knowledge has a cutoff date. After that, they’re guessing.
RAG solves this by retrieving relevant information from external sources and injecting it into the LLM’s context at query time.
The analogy I use: the LLM is a very smart person with amnesia. They can reason, write, analyze, and create. But they don’t remember anything specific. RAG is the notebook they carry around. Before answering any question, they flip through the notebook, find the relevant pages, read them, and then answer.
How RAG works. The 7-step pipeline:
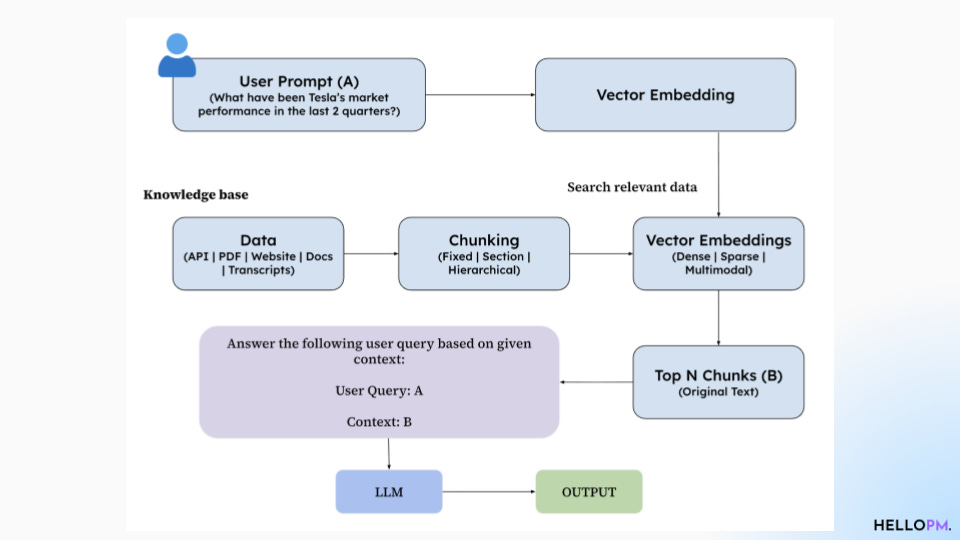
Step 1: Ingest your data. Take your documents, knowledge base, FAQs, whatever. This could be PDFs, web pages, database entries, Notion docs, meeting transcripts.
Step 2: Chunk it. This step makes or breaks your RAG system. Break the data into smaller pieces. The decisions here have outsized impact on output quality.
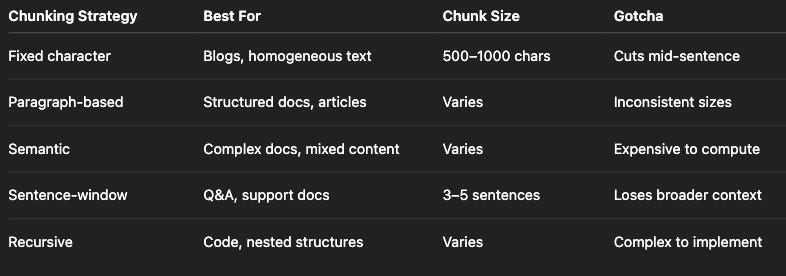
Critical: always add overlap between chunks. 10-20% overlap prevents context loss at boundaries. If a key fact spans two chunks without overlap, neither chunk has the complete information.
Step 3: Vectorize (embed). Convert each chunk into a numerical vector using an embedding model. Use the SAME embedding model for all chunks. This sounds obvious, but I’ve seen teams use different embedding models for different document types and then wonder why search quality is terrible. Different models create different vector spaces. You can’t compare vectors from different models.
Step 4: Store in a vector database. Put the vectors in a specialized database. Popular options: Pinecone, Weaviate, Chroma, Qdrant, pgvector (if you want to keep it simple with Postgres).
Step 5: At query time, retrieve. Convert the user’s question into a vector (using the SAME embedding model), search the database for the most similar chunks (Top-K retrieval, usually K=3 to K=10). This is called “semantic search” because it matches meaning, not keywords.
Step 6: Inject into the prompt. Take those retrieved chunks and add them to the LLM’s context window:
<system_prompt>
You are a customer support agent. Answer the user's question
based ONLY on the provided context. If the context doesn't
contain the answer, say "I don't have information about that."
</system_prompt>

<context>
[Retrieved chunk 1: Return policy for electronics...]
[Retrieved chunk 2: Warranty terms and conditions...]
[Retrieved chunk 3: Shipping and delivery timelines...]
</context>

<user_question>
Can I return my headphones after 30 days?
</user_question>
Step 7: Generate. The LLM now has the question AND the relevant context. It generates a grounded, informed response.
Where RAG goes wrong. The debugging framework:
When your RAG system gives bad answers, don’t start by blaming the model. Debug from top to bottom:
Data quality → Is the source data accurate and well-formatted? Run a human review of 20 random chunks. If they don’t make sense to a human, they won’t make sense to the model.
Chunking strategy → Are the chunks the right size? Too big (>1000 tokens) wastes context window space. Too small (<100 tokens) loses meaning. Are important facts split across chunk boundaries?
Embedding quality → Are you using a good embedding model? OpenAI’s text-embedding-3-small is fine for most use cases. For specialized domains, consider domain-specific embedding models.
Search quality → Are you retrieving the RIGHT chunks? Test this: run 20 user queries, look at the retrieved chunks manually. If the chunks aren’t relevant, the best model in the world won’t save you. Consider hybrid search (dense vectors for semantic matching + sparse vectors like BM25 for keyword matching). Many production systems use both.
Re-ranking → After initial retrieval, use a re-ranker model to re-order chunks by relevance. This adds ~100ms of latency but can significantly improve the quality of the top-K results.
Prompt quality → Does your system prompt tell the model how to use the retrieved context? Add explicit instructions: “Base your answer ONLY on the provided context.” Without this, the model will happily mix retrieved context with its own training data.
Model quality → Only after checking everything above should you consider upgrading the model.
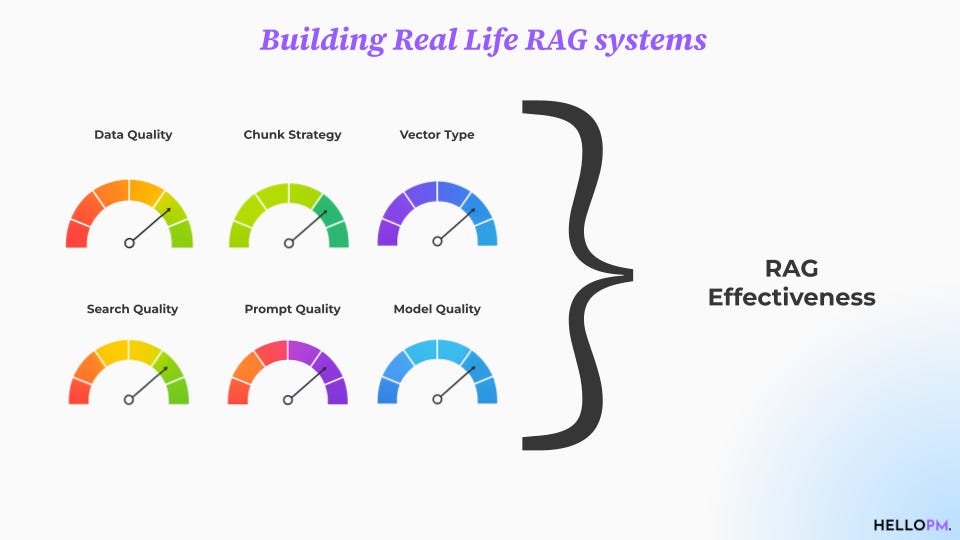
Teams that debug bottom-up (starting with the model) waste weeks trying different LLMs when the real problem is their chunking strategy.
Measuring RAG quality with real metrics:
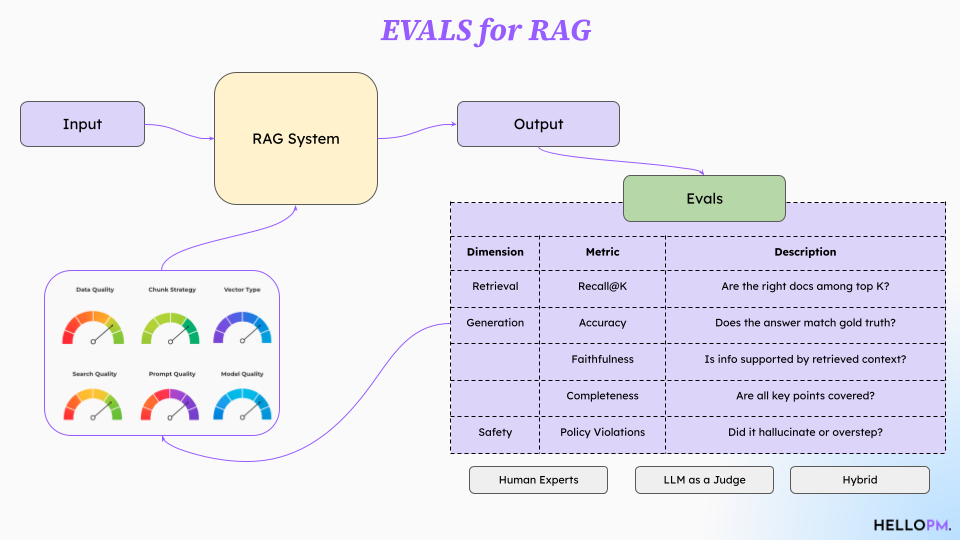
Don’t just vibe-check your RAG outputs. Use proper retrieval metrics:
MRR (Mean Reciprocal Rank): How well does the system place the first relevant result? If the correct chunk is the 3rd result, MRR = 1/3. You want this close to 1.0.
NDCG (Normalized Discounted Cumulative Gain): How well does the system rank ALL relevant results? Takes position into account. Higher is better.
Recall@K: Of all the relevant chunks that exist, what percentage did you retrieve in the top K? If there are 5 relevant chunks and you retrieved 3 in your top-5, recall@5 = 60%.
If your MRR is below 0.5, your retrieval is the bottleneck. Fix it before touching anything else.
NotebookLM is RAG made beautifully simple. Google’s NotebookLM is probably the cleanest consumer-facing RAG product. Upload documents (PDFs, Google Docs, YouTube videos, web links). NotebookLM chunks and indexes them. Then you can ask questions, generate study guides, create FAQs, or produce podcast-style audio discussions, all grounded in YOUR documents.
Google’s engineers now call this “source grounding” instead of RAG. The terminology is evolving, but the principle is the same.
The key innovation in NotebookLM isn’t the RAG itself. It’s the UX. Instead of a blank chat box, NotebookLM gives you pre-built templates: “Generate a Study Guide,” “Create an FAQ,” “Make a Podcast.” Each template is a carefully crafted system prompt optimized for that specific output format. This is product thinking applied to RAG. The user doesn’t need to know what to ask. The product suggests what they might want.
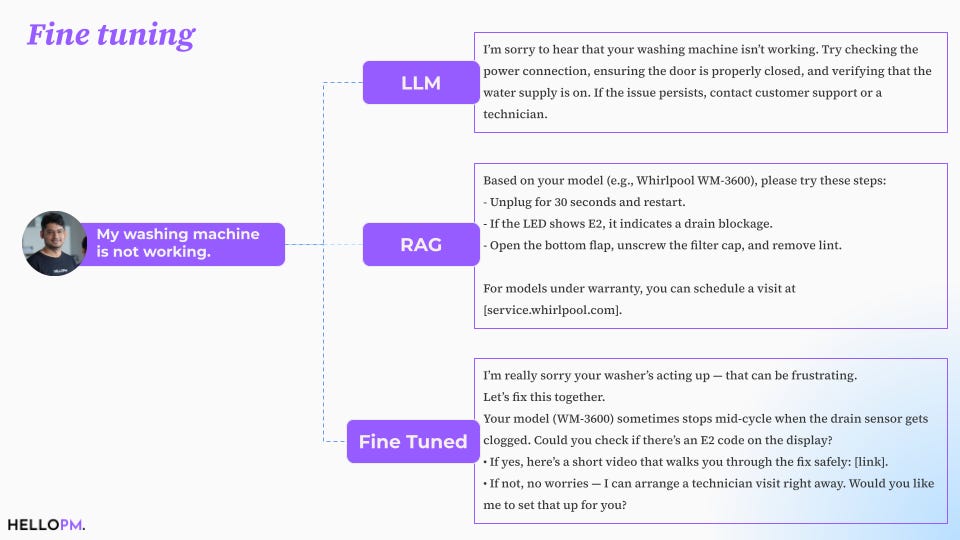
One more thing about RAG: it solves knowledge, not behavior. If you want your LLM to know about your company’s return policy, use RAG. If you want your LLM to speak in a specific tone, respond in a specific format, or behave a specific way, RAG won’t help. That’s what fine-tuning is for.
RAG = Knowledge. Fine-tuning = Behavior.
Know the difference.
3. How Notion AI and Cursor actually work.
Two products. Two very different approaches to the same fundamental problem: how do you integrate an LLM into a user’s workflow?
Notion AI: AI as an enhancement to an existing product.
Notion existed for years before adding AI. Millions of users, mature product, clear workflows. The AI had to fit into that workflow, not replace it.
Notion AI’s approach (simplified): “You are a writing assistant inside Notion. Match the document’s tone and style. Offer contextual edits, never rewrite entirely. Keep suggestions brief and relevant. Never invent data.”
Notice what this does. It constrains the LLM to be a helper, not a creator. Notion’s users are writers and knowledge workers who take pride in their work. An AI that rewrites everything from scratch would feel threatening. An AI that enhances what you’ve already written feels empowering.
Notion AI’s key design decisions and why they matter:
Context-aware generation. Notion AI reads the page you’re on, the database it belongs to, and the surrounding pages in the workspace. When you ask it to “continue writing,” it matches the tone, style, and structure of what’s already there. This isn’t just sending your text to GPT. It’s RAG against your own workspace.
Inline, not separate. The AI works within your document, not in a separate chat window. This keeps you in flow state. The moment you force a user to context-switch to a chat panel, you’ve broken their workflow.
Suggestion-based, not execution-based. It suggests. You decide. The user is always in control. This is the right choice for a tool where the user is the expert (they know what they want to say) and the AI is the assistant (it helps them say it better).
Pre-built actions, not blank prompts. “Summarize,” “Translate,” “Fix grammar,” “Make longer,” “Make shorter.” These are buttons, not prompts. Notion studied what users actually ask AI to do and turned the top requests into one-click actions. This is the NotebookLM approach applied to writing. Don’t make users figure out how to prompt. Give them the prompts as buttons.
Cursor: AI as the core of a new product.
Cursor took a completely different path. They forked VS Code (the most popular code editor) and rebuilt it with AI at the center. Not a plugin. A full IDE where AI understands your entire codebase.
How Cursor’s codebase indexing actually works:
When you open a project in Cursor, here’s what happens behind the scenes:
Shadow workspace creation. Cursor creates a local index of your entire project.
Code chunking. Every file, function, class, and variable is broken into chunks.
Embedding generation. Each chunk is converted to an embedding using a code-specific model.
Semantic index. These embeddings are stored in a local vector database, creating a searchable map of your entire codebase.
At query time, context compression. When you ask Cursor to “add authentication to the API,” it searches this index (potentially 10M+ tokens of code), finds the relevant files (~500K tokens), scores by relevance (~50K tokens), then compresses to the critical sections (~8K tokens that fit in the prompt).
That 10M-to-8K compression is the magic. Cursor uses RAG on code, and the quality of that retrieval determines whether the AI suggestion is useful or useless.
Cursor’s multi-agent architecture (Cursor 2.0):
As of 2025, Cursor introduced “background agents” that can coordinate multiple AI agents working in parallel. Here’s how it works for a complex feature request:
Agent 1 reads the relevant backend files and generates API endpoints
Agent 2 reads the frontend components and generates UI changes
Agent 3 generates tests for the new code
A coordinator agent reviews all changes for consistency
Each agent works in an isolated environment (like a git branch), so if one agent’s work is bad, you reject it without affecting the others. This is how agentic systems should be designed: parallel, isolated, with human review at the end.
Cursor’s privacy model as a product feature:
Free tier: Cursor can use your code snippets for model improvement. Paid tier: Zero Data Retention (ZDR). No code is stored. This is clever product design. The privacy concern (”will they train on my code?”) becomes a reason to upgrade rather than a reason to churn.
What you can steal from both:
From Notion: If you’re adding AI to an existing product, respect the user’s existing workflow. Constrain the AI to enhance, not replace. Turn common prompts into buttons.
From Cursor: If you’re building AI-native, give the AI deep context through aggressive indexing. But always keep the human in control. Show diffs, support rollback, make rejection easy.
Both products validate the same principle: the best AI products are co-pilots, not auto-pilots.
4. Fine-tuning and when it actually makes sense.
Everyone wants to fine-tune. Most people shouldn’t. I say this after watching dozens of teams waste weeks and thousands of dollars on fine-tuning when prompt engineering would have solved their problem.
Fine-tuning means taking a pre-trained LLM and training it further on your specific data. You’re adjusting the model’s actual parameters to behave differently for your use case.
The decision framework. Ask these questions in order:
Can prompt engineering solve this? If yes, stop. You’re done. Ship it.
Can prompt engineering + RAG solve this? If yes, stop. Ship it.
Is the problem about knowledge or behavior?
Knowledge (the model doesn’t know something) → Use RAG. Not fine-tuning.
Behavior (the model doesn’t act the way you want) → Maybe fine-tuning. Keep reading.
Do you have enough training data? You need at least 50-100 high-quality examples. 500+ is better. If you don’t have this, go back to prompt engineering.
Is this a high-volume use case? Fine-tuning has a one-time cost but reduces per-query costs. If you’re running fewer than 5,000 queries per month, the ROI rarely works out.
When fine-tuning makes sense (with real math):
Scenario: Customer support chatbot needing brand-specific tone.
Prompt engineering approach: 2,000 tokens of tone instructions in every system prompt.
Cost per query: 2,000 extra tokens x $2.50/million = $0.005
Monthly cost at 100,000 queries: $500/month just for tone tokens
Annual cost: $6,000
Fine-tuning approach: Train on 10,000 past conversations. One-time cost.
Training cost: ~$200-500 (using PEFT/LoRA)
Per-query savings: those 2,000 tone tokens are no longer needed
Annual savings: ~$5,500
Break-even: roughly 1-2 months
At this volume, fine-tuning clearly wins. But at 1,000 queries/month, the annual cost of prompt engineering is $60. Not worth the complexity of fine-tuning.
When fine-tuning does NOT make sense:
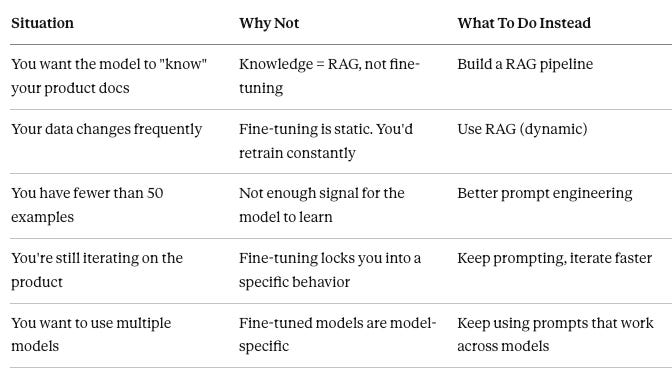
Full fine-tuning vs. PEFT/LoRA:
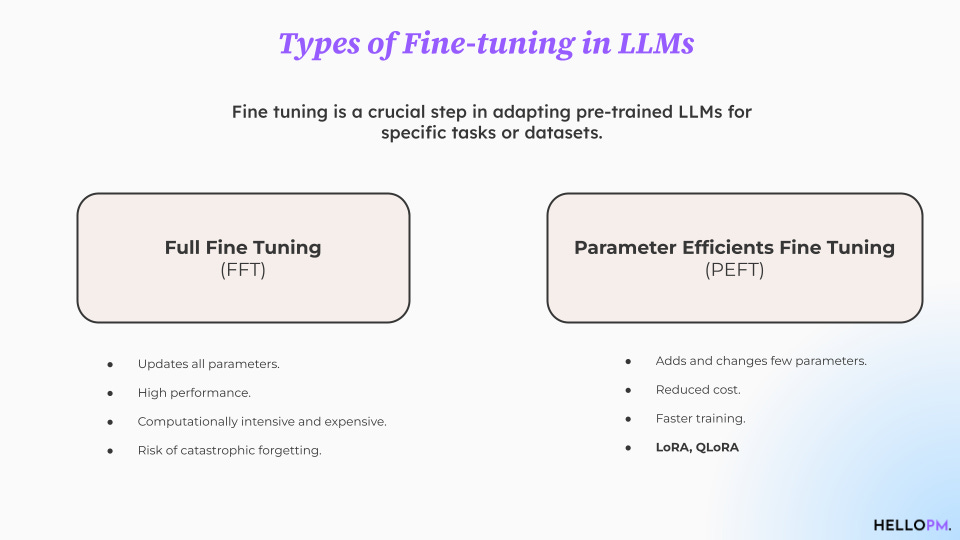
Most teams use Parameter-Efficient Fine-Tuning (PEFT), specifically LoRA (Low Rank Adaptation). Instead of updating all of the model’s billions of parameters (astronomically expensive), LoRA updates a tiny subset.
Full fine-tuning: Updates ALL parameters. 10-100x the cost. Rarely needed.
LoRA: Updates <1% of parameters. Nearly as effective. This is what you should use.
The Superman vs. Doctor analogy: A general-purpose LLM like GPT is Superman. It can do everything reasonably well. But when you’re sick, you don’t need Superman. You need a doctor. A fine-tuned small model for a specific domain is that doctor. Specialized, efficient, and cheaper to operate.
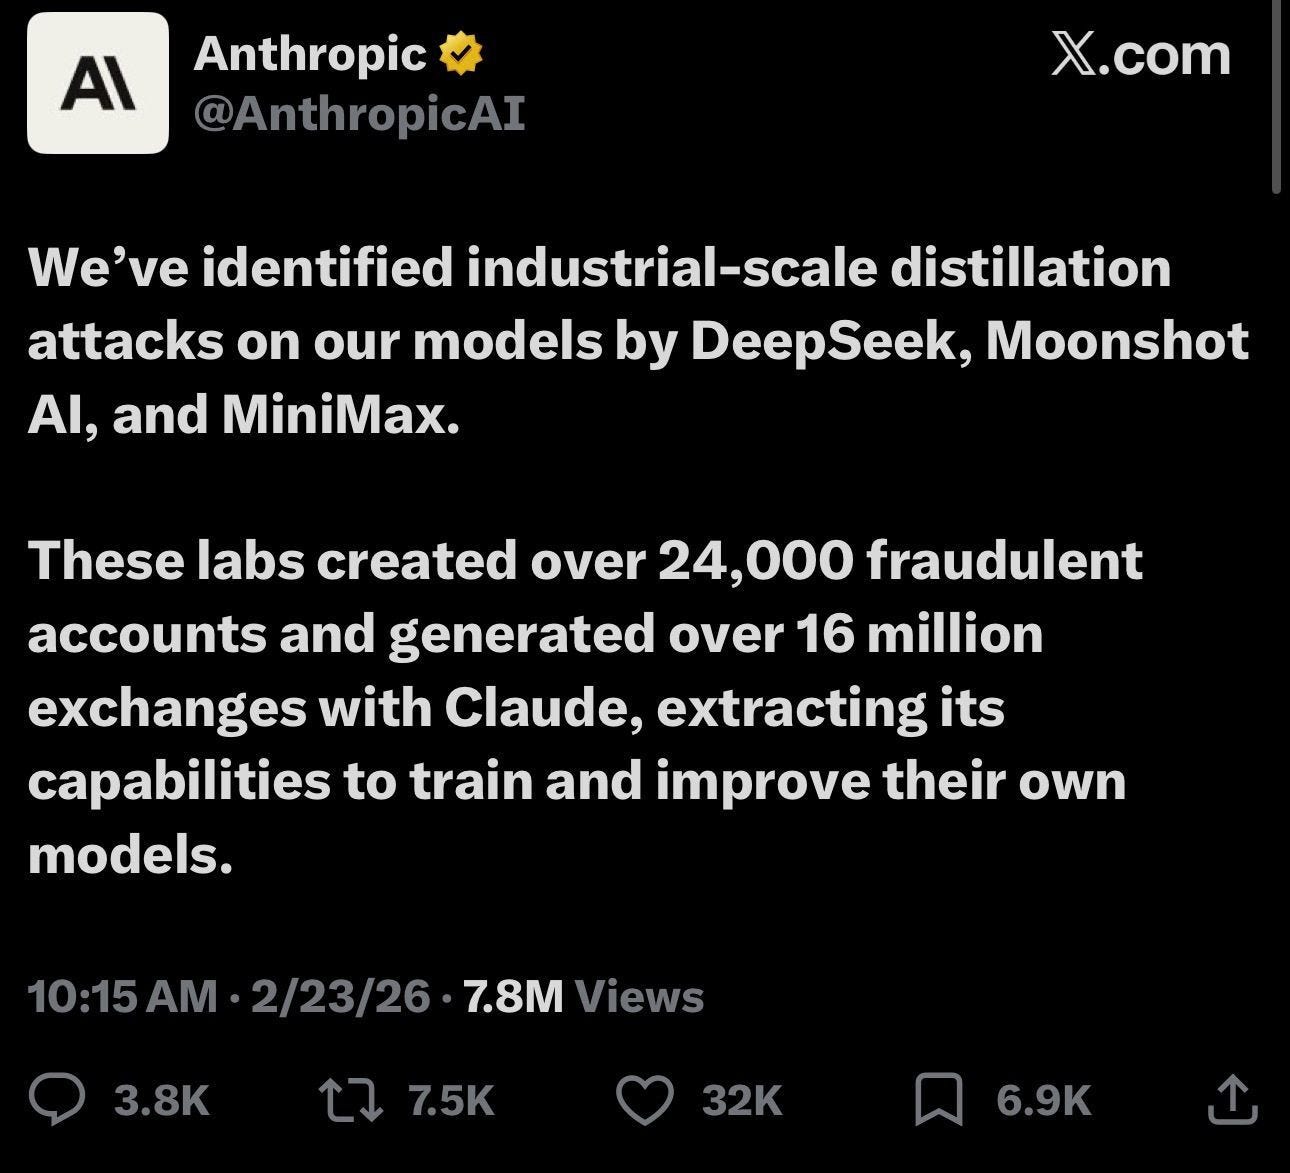
The practical play for most teams in 2026: Use a large model (GPT-4o, Claude Sonnet) to generate high-quality training data. Then fine-tune a small, cheap model (Llama, Gemma, GPT-4o-mini) on that data. You get 80-90% of the large model’s quality at 1/10th to 1/100th of the cost. This is called distillation, and it’s how most production AI products actually work at scale.
Anthropic seems to be worried about it!
Part 4: Agents and the Next Wave
1. Introducing Agentic AI.
Everything we’ve covered so far is about LLMs responding to single queries. You ask a question, you get an answer. One shot.
Agents are different. An agent is an LLM that can plan, use tools, and take multiple actions to accomplish a goal. It’s the shift from “LLM as a tool” to “LLM as a worker.”
Think about the difference between Google Search and a research assistant. Google gives you links. A research assistant takes your question, breaks it into sub-questions, searches multiple sources, cross-references findings, synthesizes insights, and gives you a report. That’s the difference between a basic LLM call and an agent.
Three components of every agent:
1. Intelligence (the brain). The LLM itself. Claude, GPT, Gemini. Handles understanding, reasoning, and decision-making. The quality of the brain determines how well the agent plans.
2. Action (the hands). The tools the agent can use: web search, database queries, file creation, API calls, code execution. An agent without tools is just a chatbot. Tools are what give it the ability to act.
Practical example: Harvey’s legal agent has these tools:
Document parser (extracts text from PDFs)
Clause extractor (identifies specific clause types)
Risk pattern matcher (compares against known risk patterns)
Language generator (suggests alternative language)
Summary generator (creates executive summaries)
Each tool is a specific, well-defined function. The agent decides which tools to call and in what order.
3. Orchestration (the nervous system). The framework that coordinates everything. Manages tool calling sequences, handles memory, manages error recovery, enforces guardrails. Platforms like LangGraph, n8n, and Relay handle this.
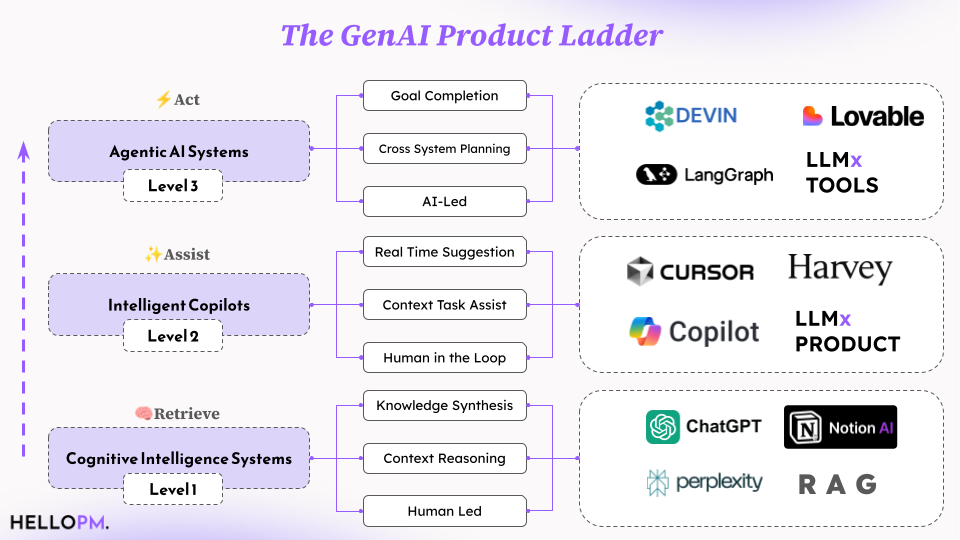
Three levels of AI autonomy:
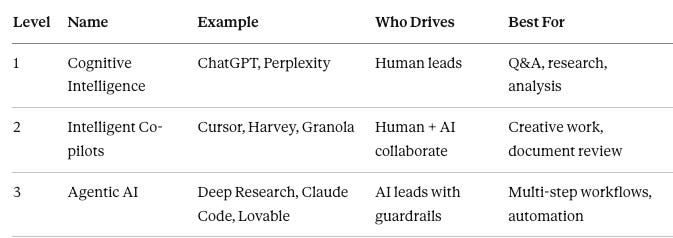
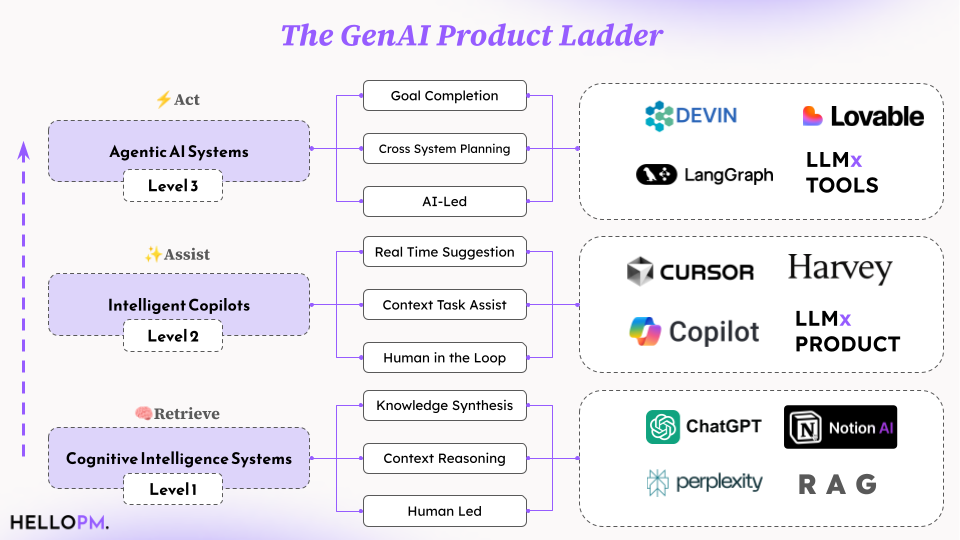
The key insight: agency and control are the two knobs you set. More agency = less human control. The right setting depends on three factors:
Cost of errors. Code review (easy to fix) vs. legal filing (hard to undo). Higher cost = lower agency.
User expertise. Developers can evaluate code suggestions. Non-technical users can’t evaluate architectural decisions. Lower expertise = lower agency.
Task complexity. Single-step tasks don’t need agents. Multi-step tasks with dependencies do.
Guardrails vs. Control. This distinction matters.
Even a fully agentic system has guardrails (safety rules, boundaries, constraints). Control is about who drives the workflow.
A boss who sets company policies (9-5 hours, code of conduct, security protocols) is setting guardrails. A boss who tells you exactly what to type in every email is exercising control. The best agents have strong guardrails and high agency. They can act independently, but within well-defined boundaries.
In practice, this means:
Guardrails: “Never execute a financial transaction without user confirmation.” “Never access files outside the project directory.” “Always cite sources.”
Control: “Wait for the user to approve each step before continuing.” “Only generate code when explicitly asked.”
Most products start with high control (Level 1-2) and gradually increase agency as they build trust and improve their evaluation systems. Don’t skip to Level 3 because it sounds impressive. Earn it.
2. Building AI Agents. How Deep Research works.
Let’s break down how one of the most impressive agent patterns works: Deep Research (available on Gemini, Claude, ChatGPT, and Perplexity).
When you give Deep Research a complex question like “Compare approaches to AI regulation across the US, EU, and China, with specific attention to how each framework handles open-source models,” here’s what actually happens:
Step 1: Planning (the agent’s “thinking” phase).
The main agent (the “orchestrator”) takes your question and creates a research plan. It decomposes the question into sub-tasks:
Task 1: Research US AI regulatory framework (executive orders,
        proposed legislation, state-level laws)
Task 2: Research EU AI Act specifics (risk categories,
        compliance requirements, timelines)
Task 3: Research China's AI regulations (algorithm rules,
        generative AI measures, deep synthesis provisions)
Task 4: For each framework, extract specific provisions
        about open-source models
Task 5: Synthesize findings into comparative analysis
This planning step is itself an LLM call. The orchestrator prompt includes instructions like: “Break the research question into 3-7 independent sub-tasks that can be executed in parallel. Each sub-task should have a clear objective and a list of search queries to execute.”
Step 2: Parallel execution with sub-agents.
Each sub-task gets its own agent instance with tools:
Web search (Brave, Google, Bing)
Web page reader (fetches and extracts text from URLs)
Note-taker (saves findings to memory)
Sub-agents work simultaneously. Agent 1 researches US policy while Agent 2 researches EU policy while Agent 3 researches China. This parallelism is what makes Deep Research fast despite its complexity.
Step 3: Iterative search and validation.
Each sub-agent doesn’t just search once. It follows a loop:
Search with initial query
Read top results
Extract relevant information
Identify gaps in findings
Generate new search queries to fill gaps
Repeat until findings are sufficient (or max iterations reached)
This is the part most people miss about agents. It’s not “search once, summarize.” It’s “search, read, identify what’s missing, search again.” A single sub-agent might execute 5-15 search queries before it’s satisfied.
Step 4: Memory management (the critical infrastructure).
LLMs have limited context windows. A sub-agent that reads 20 web pages can easily accumulate 100,000+ tokens of raw text. That won’t fit in a single prompt.
Solution: Each sub-agent saves structured notes to external memory (a database or file system), not the raw web pages. The notes are condensed summaries of key findings with source URLs. When the orchestrator needs to synthesize, it loads these structured notes, not the raw data.
This is why agentic systems need good memory architecture. Without it, either the context window overflows (agent crashes) or early findings get lost (agent produces incomplete work).
Step 5: Synthesis and quality control.
The orchestrator loads all sub-agent findings and generates the final report. But before delivering it, a quality check runs:
Are all sub-tasks addressed?
Are there contradictions between findings?
Are all claims supported by cited sources?
Are there obvious gaps?
If the quality check fails, the orchestrator spawns additional sub-agents to fill the gaps.
Applying the agent pattern to Harvey’s legal AI:
Harvey uses a similar architecture for document review, but the tools and domain are different:
Orchestrator receives: 150-page commercial contract

Sub-agent 1: Extract all indemnification clauses → Compare
             against risk patterns → Flag deviations
Sub-agent 2: Extract all termination provisions → Check for
             standard terms → Flag missing provisions
Sub-agent 3: Extract all IP assignment clauses → Compare
             against firm templates → Suggest revisions
Sub-agent 4: Extract payment terms → Validate consistency
             across document → Flag ambiguities

Orchestrator: Synthesize all findings → Risk-rank →
              Generate executive summary → Present to lawyer
The lawyer sees a structured risk report with citations to specific clauses. They review, approve or override the AI’s analysis, and move on. A process that used to take 4-6 hours now takes 30-45 minutes. When lawyers bill at $500-1,000/hour, the value proposition is obvious.
Harvey charges based on this workflow value, not on token consumption. Their pricing reflects the value of the work done (saving hours of lawyer time), not the compute cost (a few dollars in API calls). This is a critical lesson for anyone building AI products: price on value delivered, not on tokens consumed.
3. Why agents break (and how to fix them).
Agents look magical in demos. In production, they break in specific, predictable ways. Here’s each failure mode with concrete numbers and fixes.
Problem 1: Compounding errors.
When an agent takes 10 sequential steps, and each step has a 95% accuracy rate, the overall accuracy is:
0.95^10 = 59.9%
That’s a 40% failure rate. At 20 steps: 0.95^20 = 35.8%. Two-thirds of your agent runs will have at least one error somewhere in the chain.
Fixes:
Keep chains short. Decompose into 3-5 step sequences, not 15-20.
Add verification checkpoints. After every 2-3 steps, have a second LLM (or code-based check) verify the intermediate output. This resets the error accumulation.
Use parallel, not sequential. Instead of Step 1 → Step 2 → Step 3 → ... → Step 10, run Steps 1-5 in parallel, verify, then run Steps 6-10 in parallel. Errors in one branch don’t propagate to others.
Implement rollback. Cursor does this brilliantly with its “milestone” system. At each checkpoint, save the state. If a later step fails, roll back to the last good checkpoint instead of restarting from scratch.
Problem 2: Context window overflow.
Agents that process many documents or do extensive research accumulate tokens fast. A 20-page document is ~10,000 tokens. Read 10 documents and you’ve got 100,000 tokens. Most model context windows are 128K-200K tokens, and quality degrades well before you hit the limit (remember: information in the “middle” gets lost).
Fixes:
Summarize-then-store. Don’t keep raw documents in context. Have the agent summarize key findings and store the summaries. A 10,000-token document becomes a 500-token summary.
Sliding window. Only keep the most recent N steps in context. Store older context externally and retrieve it if needed (this is RAG applied to the agent’s own memory).
Hierarchical memory. Short-term memory (current context window) for the active task. Long-term memory (vector database) for past findings. The agent queries long-term memory when it needs historical context.
Problem 3: Cost explosions.
Real numbers from a production agent I analyzed:
Deep research query:
- Orchestrator planning: 1 call, ~2K tokens in, ~1K out
- 5 sub-agents × 8 searches each = 40 search API calls
- 5 sub-agents × 5 page reads each = 25 page reads
  (~5K tokens each = 125K input tokens)
- 5 sub-agent summaries: 5 calls, ~10K tokens in, ~2K out each
- Final synthesis: 1 call, ~15K tokens in, ~5K out
- Quality check: 1 call, ~10K tokens in, ~1K out

Total: ~200K input tokens + ~20K output tokens
Cost at GPT-4o rates: ~$0.80 per research query
At 10,000 queries/day: $8,000/day = $240,000/month
Fixes:
Model routing. Not every step needs your most expensive model. Use GPT-4o-mini for search query generation, page summarization, and simple classification. Reserve GPT-4o or Claude Sonnet for planning and synthesis. This can cut costs by 60-70%.
Cache aggressively. If multiple users research similar topics, cache the sub-agent findings. A semantic cache that matches queries with >0.9 similarity can reuse past research.
Limit iterations. Set maximum search iterations per sub-agent (e.g., max 5 searches). Diminishing returns kick in fast.
Batch when possible. If multiple users submit research queries in the same hour, batch similar sub-tasks and share findings.
Problem 4: Tool failures and error cascades.
Agents depend on external tools. When a web search API returns a 429 (rate limited), or a database query times out, or a parsed web page returns garbage HTML, the agent needs to handle it. Most agents don’t, and the error cascades.
Fixes:
Retry with exponential backoff. For transient errors (timeouts, rate limits), retry 2-3 times with increasing delays.
Fallback tools. If Brave search fails, try Google. If Google fails, try Bing. Always have a backup.
Graceful degradation. If a sub-agent can’t complete its task after retries, it should return what it found with a note: “Partial findings. Could not access [sources].” The orchestrator can then decide whether to retry, skip, or flag for human review.
Timeout budgets. Set maximum execution time per agent (e.g., 60 seconds per sub-agent, 5 minutes total). If an agent exceeds its budget, terminate and return partial results.
Problem 5: The loop problem.
Sometimes agents get stuck. They try a search, get irrelevant results, rephrase, get different-but-still-irrelevant results, rephrase again, and loop indefinitely. Each loop costs money and wastes time.
Fixes:
Maximum iteration limits. Hard stop after N attempts (typically 3-5).
Similarity detection. Compare the current approach to previous approaches. If the similarity is >0.8, force a completely different strategy instead of a minor rephrase.
Escalation. After max iterations, escalate: “I couldn’t find reliable information about [topic] after [N] attempts. Here’s what I found so far. Would you like me to try a different approach?”
Part 5: The Unglamorous Reality
1. Cost, latency, and the tradeoffs nobody talks about.
This is where most “how to build AI” guides stop being useful. They’ll teach you about prompts and RAG and agents but won’t mention that your production costs can destroy your margins if you’re not careful.
The new economics of software.
Traditional SaaS has beautiful economics. Build once, distribute infinitely. The marginal cost of serving one more user is close to zero. Revenue scales, costs don’t.
LLM products break this model completely. Every query consumes tokens. Tokens cost money. Scaling linearly increases costs. Let me show you with real numbers.
A real cost model for a meeting summary product:
Assumptions:
- 10,000 users
- 3 meetings/day per user = 30,000 meetings/day
- Average meeting transcript: 8,000 tokens
- System prompt: 1,500 tokens
- Summary output: 800 tokens

Per-meeting cost (GPT-4o):
- Input: (8,000 + 1,500) × $2.50/1M = $0.024
- Output: 800 × $10.00/1M = $0.008
- Total per meeting: $0.032

Daily cost: 30,000 × $0.032 = $960/day
Monthly cost: $28,800/month
Annual cost: $345,600/year

Just for inference. No engineering salaries. No infrastructure.
No customer support. Just API calls.
Now compare: if you charge users $15/month, your 10,000 users generate $150,000/month in revenue. Your inference cost is $28,800/month. That’s a 19.2% cost-of-goods-sold just for the AI. Add hosting, support, and salaries, and your margins are thin.
The same product with GPT-4o-mini:
Per-meeting cost (GPT-4o-mini):
- Input: 9,500 × $0.15/1M = $0.0014
- Output: 800 × $0.60/1M = $0.0005
- Total per meeting: $0.0019

Daily cost: 30,000 × $0.0019 = $57/day
Monthly cost: $1,710/month
Annual cost: $20,520/year
That’s a 94% cost reduction. The quality difference for meeting summaries? Marginal. Maybe 5-10% worse on complex technical discussions, but for most meetings, GPT-4o-mini is more than sufficient.
This is why model routing is so important. You don’t need GPT-4o for every task.
The three-way tradeoff: Cost vs. Latency vs. Quality.
You can optimize for two. The third will suffer.
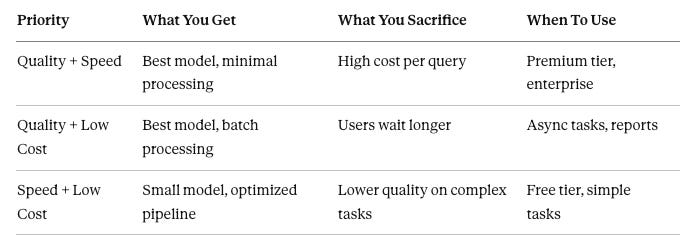
Seven practical cost optimization strategies (in order of implementation):
1. Optimize your prompts first (free). Review your system prompt. Is every token necessary? Can you say the same thing in fewer words? A team I worked with cut their system prompt from 3,200 tokens to 1,100 tokens with no quality loss. That’s a 66% reduction in per-query prompt costs.
2. Implement model routing (medium effort, huge impact). Build a classifier (can be rule-based or a tiny LLM) that examines each query and routes it:
Simple factual questions → GPT-4o-mini
Complex analysis → Claude Opus 4.6
Code generation → Claude Opus 4.6
Creative writing → GPT-5
Most production teams route 80-95% of queries to cheaper models. Only the hard cases go to the expensive ones.
3. Cache aggressively (medium effort, significant savings). Two levels of caching:
Exact match cache: Same query → same response. Free to serve repeated queries.
Semantic cache: Similar queries (cosine similarity >0.92) → cached response. Takes more engineering but catches paraphrased questions. Industry benchmarks show semantic caching can cut API costs by up to 73%.
4. Trim your context window (low effort, moderate savings). Don’t send the entire document when the user asks about one section. Use RAG to retrieve only the relevant chunks. If your RAG retrieves 5 chunks at 200 tokens each (1,000 tokens), that’s dramatically cheaper than sending the entire 10,000-token document.
5. Batch non-urgent requests (low effort for async tasks). If your product generates daily summaries, weekly reports, or async analysis, batch these requests. Process them during off-peak hours. Some API providers offer lower rates for batch processing.
6. Fine-tune smaller models for high-volume tasks (high effort, long-term savings). If you have a specific, high-volume task (classification, extraction, formatting), fine-tune GPT-4o-mini or an open-source model like Llama on GPT-4o-generated examples. You get 80-90% of the quality at a fraction of the cost.
7. Self-host for extreme scale (highest effort, maximum control). At very high volumes (millions of queries/day), self-hosting open-source models (Llama, Mistral) on your own infrastructure can be cheaper than API calls. But the engineering overhead is significant. Only do this when API costs are genuinely your biggest expense line.
The Granola cost lesson:
Granola’s bot-free architecture isn’t just a privacy decision. It’s a cost decision.
Bot-based meeting tools pay for a remote participant connection to the video platform, video/audio streaming, cloud storage for recordings, and post-processing. Granola captures audio locally, transcribes it, and deletes it.
They eliminated three major cost drivers and passed those savings directly to their pricing ($14/month vs. competitors at $20-30/month).
When you’re designing your AI product’s architecture, ask: “Where am I paying for compute that the user doesn’t directly benefit from?” Then eliminate it.
2. Evaluations. The skill that separates serious builders from everyone else.
If you are a video person, here is The Evaluation Masterclass for you:
I’m going to say something that might surprise you: evaluations are more important than the model you choose. More important than your prompt. More important than your RAG pipeline.
Here’s why. Without good evaluations, you’re flying blind. You ship a product, users complain, you tweak the prompt, the complaints change but don’t stop, you tweak again, and you’re stuck in a loop of guessing. Good evaluations tell you exactly what’s working, what’s not, and where to focus.
The best AI teams practice what Eugene Yan and the Applied LLMs authors call eval-driven development: evaluations guide development from day one. You start by evaluating a baseline (even a simple prompt), then every change, every tweak, every iteration is measured against your eval suite. No vibes. No “it seems better.” Numbers.
Two types of evaluations:
Offline evaluations happen before launch. Like QA for traditional software. You run your product against a test set and measure performance. This is your safety net before you ship.
Online evaluations happen after launch. Like production monitoring. You track how the product performs with real users in real conditions. This catches the problems offline testing misses: unusual inputs, edge cases you didn’t anticipate, model drift over time.
Step 1: Create a golden dataset.
This is your answer key. A collection of representative inputs with known correct (or at a minimum, acceptable) outputs.
What goes in a golden dataset:
Category % of Dataset Purpose Example Happy path 50% Normal usage Standard meeting summary Edge cases 20% Boundary conditions Meeting with heavy crosstalk, technical jargon Adversarial 15% Attempts to break the system Prompt injection, off-topic requests Stress test 15% Performance under pressure Very long documents, multiple languages
Aim for 50-200 test cases to start. You’ll add more over time as you discover new failure modes in production.
Sources for golden dataset examples:
Historical user queries and verified good responses
Expert-created examples (have a domain expert write ideal outputs)
Synthetic data (use a powerful LLM to generate test cases, then have humans verify)
Production failures (every time a user reports a bad output, add it to the dataset)
Step 2: Define metrics that actually matter.
Different products need different metrics. Here’s a framework:
For summarization products (Granola, meeting tools):
Completeness: did the summary capture all key decisions and action items?
Accuracy: are all stated facts correct?
Conciseness: is the summary appropriately short?
Attribution: can every claim be traced to the source material?
For code generation products (Cursor):
Correctness: does the code compile and run?
Functionality: does it do what was asked?
Style consistency: does it match the codebase’s existing patterns?
Security: does it introduce vulnerabilities?
For document analysis products (Harvey):
Recall: did it identify all relevant clauses/risks?
Precision: did it avoid flagging non-issues?
Accuracy of risk ratings: are High/Medium/Low ratings correct?
Quality of suggestions: are recommended changes appropriate?
Step 3: Choose your evaluation method.
You have three tools. Use all of them.
Code-based evaluations (assertions). Automated checks for objective criteria. Fast, cheap, deterministic.
# Example assertions for a meeting summary tool:

def test_summary_quality(transcript, summary):
    # Check: all mentioned participants appear in summary
    participants = extract_participants(transcript)
    for person in participants:
        assert person in summary, f"Missing participant: {person}"

    # Check: summary is within length bounds
    word_count = len(summary.split())
    assert 50 <= word_count <= 300, f"Summary too long/short: {word_count} words"

    # Check: action items are formatted correctly
    action_items = extract_action_items(summary)
    for item in action_items:
        assert item.has_owner, "Action item missing assignee"
        assert item.has_deadline or item.has_status, "Action item missing timeline"

    # Check: no hallucinated URLs
    urls = extract_urls(summary)
    for url in urls:
        assert url_exists_in_transcript(url, transcript), f"Hallucinated URL: {url}"
LLM-as-judge. Use a separate LLM to evaluate outputs. This captures subjective quality that code checks can’t measure.
Evaluate the following meeting summary on these criteria.
Rate each 1-5 and provide a one-sentence justification.

Criteria:
1. Accuracy: Are all facts in the summary supported by the transcript?
2. Completeness: Does the summary cover all key topics discussed?
3. Actionability: Are next steps and decisions clearly stated?
4. Tone: Is the summary professional and neutral?
5. Conciseness: Is the summary appropriately brief without losing important details?

Transcript: [provided]
Summary: [provided]

Return JSON: {"accuracy": {"score": N, "reason": "..."}, ...}
Pro tip from the Applied LLMs authors: Use CoT + few-shot examples in your LLM-as-judge prompt. Show 2-3 example evaluations (one good summary rated 5/5, one mediocre summary rated 3/5, one bad summary rated 1/5). This dramatically improves judge consistency.
Human evaluation. For high-stakes use cases, have domain experts review a random sample. Expensive and slow, but catches things both code and LLM judges miss.
The production evaluation stack: Code assertions filter the obvious failures (wrong format, missing data, invalid URLs). LLM-as-judge evaluates the subjective quality of what passes code checks. Human review samples 5-10% of what passes LLM-judge checks. This three-layer system is what production AI products use at scale.
Step 4: The eval-driven development loop.
Here’s the workflow that actually works:
Build baseline. Simple prompt, basic RAG, cheapest viable model.
Run evals. Measure against your golden dataset.
Identify the weakest metric. Is accuracy the problem? Completeness? Speed?
Diagnose the root cause. Use the RAG debugging framework from Section 7:
Bad results with good context → Fix prompt
Bad results with bad context → Fix retrieval
Good context + good prompt + still bad → Try better model
Everything good but tone is wrong → Consider fine-tuning
Make ONE change. Don’t change the prompt AND the model AND the chunking strategy at the same time. Change one variable, re-run evals, measure the impact.
Log everything. Every prompt version, every eval result, every model change. You need to be able to trace which change caused which improvement (or regression).
Repeat. This loop runs continuously, not just before launch.
Step 5: Production monitoring (online evals).
After launch, run the same evaluations on live traffic. Sample 1-5% of production queries and evaluate them automatically.
Watch for:
Quality drift: Output quality decreasing over time (can happen when the model provider updates the underlying model)
Distribution shift: Users are asking different questions than your golden dataset anticipated
Latency spikes: Response times increasing due to longer inputs or model changes
Cost anomalies: Sudden increases in token consumption
Set alerts for when any metric drops below your threshold. When it does, add the failing examples to your golden dataset and restart the eval loop.
The meta-lesson: The teams that build the best AI products aren’t the ones with the best models or the cleverest prompts. They’re the ones with the most disciplined evaluation systems. Evals are how you turn “I think it’s working” into “I know it’s working, and here’s the data.”
You can get all samples of these docs + deck in the description of this video.
Part 6: Putting It All Together
1. The full picture. From idea to production.
You’ve got all the building blocks. Let me connect them to the actual workflow.
Phase 1: Discovery (Still PM’s job. AI doesn’t change this.)
Start with the user and the problem. Not with the model. Not with the technology.
I’ve seen too many teams say “let’s add AI to our product” without answering: what user problem are we solving? This is the most common failure mode in AI product development. Technology-first thinking.
Harvey didn’t start by saying “let’s build AI for lawyers.” They started by understanding that lawyers spend 4-6 hours on routine contract review, that this work is expensive ($500-1,000/hour), repetitive, and prone to human error when done under time pressure. The AI was the solution. Not the starting point.
The discovery checklist for AI products:
[ ] What specific task does the user do today that’s painful/slow/expensive?
[ ] How does the user currently judge the quality of this task?
[ ] What’s the cost of the AI getting it wrong? (Financial? Reputational? Safety?)
[ ] Can the user tell when the AI output is wrong? (If no, you need extra guardrails)
[ ] How many times per day/week does this task happen? (Determines if AI ROI works)
[ ] What existing data do you have that could ground the AI? (Documents, databases, examples)
Phase 2: Choose your level of AI integration.
Based on discovery:
Level 1 (AI answers questions): User is in full control. AI responds to specific queries. Example: a support chatbot.
Level 2 (AI suggests, user decides): AI proposes, human disposes. Example: Cursor’s code suggestions, Harvey’s risk flags.
Level 3 (AI acts, user oversees): AI takes autonomous actions within guardrails. Example: Deep Research, automated meeting summaries.
Start at Level 1 or 2. Earn user trust before increasing autonomy.
Phase 3: Build the simplest version that works.
The GenAI Product Ladder. Climb one step at a time:
Level 4: Agents (multi-step, tool-using, autonomous)
   ↑ Add when single-turn interactions aren't enough
Level 3: Fine-tuning (behavioral changes, cost optimization)
   ↑ Add when RAG + prompting can't match needed behavior
Level 2: RAG (external knowledge, private data)
   ↑ Add when the model needs information it doesn't have
Level 1: Prompt Engineering (system prompt, few-shot examples)
   ← START HERE. Always.
Each step up adds complexity, cost, and capability. I’ve seen teams jump straight to agents when a good system prompt would have solved their problem. Don’t climb the ladder until you’ve exhausted the current step.
Phase 4: Build your evaluation system EARLY.
Don’t wait until launch. Build evals alongside your first prototype:
Create your golden dataset (start with 20 examples, grow to 100+)
Write code assertions for objective criteria
Set up LLM-as-judge for subjective quality
Define your quality thresholds
Run evals after every change
This discipline is the single biggest differentiator between teams that ship good AI products and teams that ship embarrassing ones.
Phase 5: Design for the nature of the technology.
Your UX should account for LLM behavior. Here are the 8 patterns that matter:
Avoid blank slates. Pre-populate, suggest, show examples. NotebookLM’s template buttons. Granola’s pre-meeting context. Don’t show an empty text box.
Show your sources. Cite where information came from. Let users verify. Harvey shows which clause it’s referencing. Perplexity shows which web pages it used. If your AI can’t cite its sources, users can’t trust it.
Make recovery easy. When the AI gets it wrong (it will), make correction simple. Cursor’s one-click reject. ChatGPT’s regenerate button. The fewer clicks between “this is wrong” and “try again,” the better.
Handle latency with purpose. Stream responses. Show progress states: “Searching your documents...” “Analyzing...” “Generating summary...” Turn the wait into transparency.
Collect feedback. Thumbs up/down, flags, corrections. Every piece of feedback is training data for your evaluation system. And it makes users feel heard.
Be proactive. Don’t just wait for users to ask. Suggest what they might want. Granola surfaces previous meeting context. Cursor offers completions before you ask. The best AI products anticipate, they don’t just respond.
Show confidence levels. If the AI is uncertain, say so. “Based on the available information, I’m fairly confident that...” is better than a definitive statement that turns out to be wrong.
Design the error state. What does the user see when the AI fails completely? “Something went wrong” is unacceptable. “I couldn’t find relevant information in your documents about [topic]. Try uploading additional sources or rephrasing your question.” That’s useful.
Phase 6: Ship, monitor, iterate.
Launch with your evaluation system in place. Monitor quality metrics daily. Watch for drift. Keep running your golden dataset. Add production failures to your test suite. The iteration loop in AI products is continuous. You’re not just fixing bugs. You’re constantly tuning prompts, adjusting retrieval, and reacting to how users actually use the product.
One more thing. Log your LLM inputs and outputs from day one. Every prompt, every response, every token count, every latency measurement. This data is how you debug problems, optimize costs, and build better evaluations. Teams that don’t log from the start always regret it later.
What to do next.
If you’ve made it this far, you know more about building AI products than 90% of people talking about it on LinkedIn.
But knowledge without action is just trivia. Here’s what to do with what you’ve learned.
If you’re a PM who wants to build AI products:
Do a real product teardown. Pick one product from this guide (Granola, Cursor, Harvey, NotebookLM). Use it for a week. Map every feature to the building blocks:
- What’s the system prompt doing?
- Where’s the RAG?
- What’s the human-in-the-loop design?
- How do they handle errors?
Write it up.
This exercise alone puts you ahead of most AI PMs.Build something small with an API. Take a repetitive part of your own workflow and automate it. Sign up for the OpenAI or Anthropic API. Write a system prompt. See how far prompt engineering gets you. Then add RAG if you need it. You’ll learn more from 2 hours of hands-on building than from 20 hours of reading (including this guide).
Create your first golden dataset. Pick any AI product you use. Create 20 test cases with expected outputs. Run the product against them. Score the results. Congratulations, you just did your first AI evaluation. This is the most underrated skill in AI product management.
Learn the cost model cold. Before your next product meeting, calculate the per-query cost of your AI feature. How many tokens per request? What model? Monthly cost at projected usage? Being able to answer these questions makes you a different kind of PM.
If you’re an engineer building AI products:
Build evals before features. Seriously. Set up a golden dataset and an automated evaluation pipeline before you build the feature. It’ll save weeks of debugging and prevent shipping garbage.
Master RAG before you try fine-tuning. Most use cases don’t need fine-tuning. A well-built RAG pipeline with good chunking, hybrid search, and re-ranking gets you surprisingly far.
Implement model routing on day one. Don’t hardcode a single model. Build a routing layer that can send different queries to different models. This gives you cost optimization now and flexibility later when better/cheaper models are released.
Log everything. Every prompt, response, latency, token count, and user action. Build dashboards. You’ll need this data sooner than you think.
If you’re a founder building an AI startup:
Your moat is not the model. Models are commoditized. Your moat is domain expertise, proprietary data, user experience, and distribution. Harvey’s moat is understanding legal workflows and relationships with 700+ law firms. Cursor’s moat is codebase indexing and developer UX. Build your moat around what doesn’t change when the next model drops.
Price on value, not compute. Harvey doesn’t charge by the token. They charge based on the value of the legal work. Cursor doesn’t charge by completions. They charge for developer productivity. Find the value metric for your users and price against that. If you price per token, you’re in a race to the bottom that you’ll lose.
No GPU before PMF. Don’t invest in fine-tuning, self-hosting, or custom model training until you have product-market fit. Use APIs. Stay flexible. Iterate fast. You can optimize costs after you’ve found the product that users want.
Need more resources?
Here is the 3.5-hour AI PM Masterclass.
Here is the AI evals Masterclass
This guide is a living document. AI products are evolving fast.
New models, techniques, and patterns emerge every month.
But the fundamentals, understanding your user, mastering prompts, building good RAG, evaluating rigorously, managing costs, these aren’t going to change.
The tools will evolve. The principles will stay.
Enough reading & watching, now go build something.
I’m Ankit Shukla, founder of HelloPM. I teach AI Product Management to working professionals and career switchers. If this guide was useful, share it with someone building with LLMs. And if you want to go deeper, check out our AI PM cohort programs where we do live teardowns, hands-on projects, and evaluations with real products.
Questions? Reach me at ankit@hellopm.co.
I had to come find you on Substack having read the newsletter received in my email. Thank you for this piece, really in-depth and I get to understand the why behind the AI features I test.
One of the best and most detailed AI article that insightful and high ROI. Loved it, thanks for sharing Ankit.